One 2026 traffic analysis tracked more than 500 million visits from AI bots. Across all of that traffic, requests for llms.txt added up to just 408. While this is not 408 million, it is worth paying attention to because these are the bots behind tools like ChatGPT, Perplexity, and Google’s AI search features. Yet the llms.txt file barely showed up in their activity.
That doesn’t mean the file is useless. llms.txt is real. It has a documented origin, its own specification, and a specific purpose. The bigger problem is how people talk about it. A lot of SEO advice makes it sound like every website needs one, even though the numbers don’t really support that.
So, what is llms.txt? Where did it come from? Who is actually using it? And, more importantly, does your website need one? That’s what this guide is here to answer.
Quick answer:
llms.txt is a plain Markdown file at yourdomain.com/llms.txt that gives AI systems a curated map of a site’s most important content. It isn’t a ranking factor, and doesn’t influence Google’s AI Overviews. Current traffic data shows the crawlers behind ChatGPT’s web search, Perplexity, and Google’s AI Overviews rarely fetch it. Where it genuinely matters today is AI coding assistants, agent tooling, and developer documentation sites, and not only general AI search visibility.
What Is an llms.txt File?
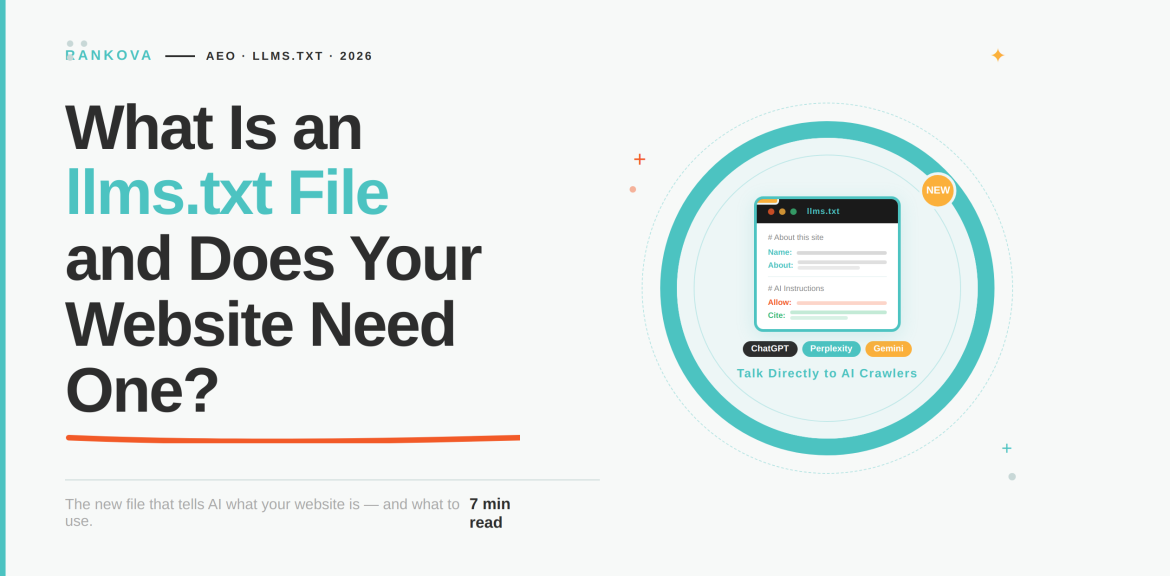
llms.txt is a plain-text Markdown file published at the root of a domain, yourdomain.com/llms.txt, that hands large language models a summary of a site’s most important content instead of forcing them to parse full HTML pages that have navigation, ads, and scripts.
An H1 with the site or project name is important. A blockquote summary and a handful of H2 sections with linked annotated resources are the rest of the convention. On the other hand, /llms-full.txt merges a site’s full documentation into one large file.
Note that this file is not an access control mechanism. Also, it can’t block or restrict any crawler. It isn’t an index, nor does it list every page on your site the way a sitemap does. The best way to think of an llms.txt file is as a hand-curated reading list.
The Origin of the llms.txt File.
Jeremy Howard, co-founder of Answer.AI, published the proposal on September 3, 2024, along with a companion specification at llmstxt.org. The reasoning was that language models have limited context windows. As such, most websites don’t fit inside them, and raw HTML is inefficient for a model to scan.
About its status, llms.txt is not a ratified standard. It carries no backing or enforcement mechanism for any crawler to honor it. That means it’s voluntary to adopt it, on each AI provider’s own terms, which is a large part of why usage today looks the way it does.
llms.txt vs. robots.txt vs. sitemap.xml
People often confuse these three files together. Well, here are their differences;
| File | What it does | Do major crawlers honor it? |
| robots.txt | Controls access and tells crawlers what they may fetch. | Yes, this is an established standard. |
| sitemap.xml | Lists every indexable URL on a site for discovery. | Yes, used broadly by search engine crawlers. |
| llms.txt | An hand-picked summary of key content, meant to be read at inference time. | Inconsistently, and rarely by the crawlers behind mainstream AI search. |
Does llms.txt Improve AI Search Visibility?
Well, let’s look at data to answer this important question;
- A large-scale traffic analysis of AI bot activity found that among the crawlers that actually drive citations, GPTBot, ClaudeBot, PerplexityBot, OAI-SearchBot, and Google-Extended, requests to /llms.txt were a statistically negligible share of total traffic. Out of hundreds of millions of tracked bot visits, fewer than 500 requests targeted the file directly.
- According to Google, they do not support llms.txt and have no plans to.
- Independent SEO analysts back this up with their own data. Seer Interactive’s server log audits for client sites found that the AI crawlers that matter for search visibility largely aren’t fetching the llms.txt file at all.
So, the honest conclusion is that if the goal is showing up more often in ChatGPT’s answers, Google’s AI Overviews, or Perplexity’s results, llms.txt is not currently a lever that moves that needle in any measurable way.
Does that mean it’s useless? Keep reading.
Who Reads llms.txt Today?
The file isn’t pointless. Rather, it’s just aimed at a narrower audience than most of the hype suggests. Studies have shown that its relevance is around agentic and developer tooling rather than consumer AI search:
- AI coding assistants and IDE agents. Tools like Cursor and Claude Code are the most consistent readers of llms.txt today. They fetch the llms.txt file to build a map of a project’s documentation quickly.
- Agent frameworks and protocols. OpenAI references the format in its Agents SDK and Agentic Commerce Protocol documentation. Anthropic includes it in its own guidance for building AI agents.
- Browser-level agentic tooling. Google’s Chrome team added an “Agentic Browsing” audit category to Lighthouse in 2026 that checks whether a site provides an llms.txt file, part of a broader push to make sites more legible to browser-based AI agents, and not to Google Search itself. Chrome’s own documentation covers what that audit checks for.
llms.txt is increasingly relevant for tools that act as agents navigating or building on a site’s content, documentation assistants, coding tools, and agentic browsers, but it has comparatively little relevance right now for the AI search and answer engines most businesses care about for visibility.
Does Your Website Need One?
The short answer is no. Most businesses don’t have to worry about llms.txt. If your goal is to show up more often in ChatGPT answers, Google’s AI Overviews, or Perplexity results, general content sites, local businesses, and most e-commerce stores will get a far better return. You should also prioritize entity clarity, extractable content structure, genuine third-party corroboration, and clean structured data. Adding llms.txt in pursuit of that goal is not a priority. You can consider it if:
- You run developer documentation or an API reference, where AI coding assistants are meaningful.
- You’re building agent or plugin integrations for platforms like OpenAI’s Agents SDK, where the format is directly referenced in the provider’s tooling documentation.
- Your product has a defined reason to expect meaningful traffic from AI agents or agentic browsers acting on your site.
How to Create an llms.txt File?
If your site genuinely fits one of the “consider it” cases above, the implementation is simple:
- Write a genuinely curated summary. It can be an H1 with your site or project name, a one- to two-sentence blockquote description, and a handful of H2 sections linking to your most important pages. You can attach a brief note on what it covers.
- Publish it at the domain root, yourdomain.com/llms.txt in plain Markdown. There is no special server configuration required beyond serving the file as plain text.
- Keep it small and hand-picked.
- Verify whether anything is reading it. Check server access logs, or a tool like Cloudflare Analytics, for requests to /llms.txt from known AI user-agents (GPTBot, ClaudeBot, PerplexityBot, Google-Extended).
- Maintain it like documentation. A stale llms.txt pointing to outdated or removed pages is arguably worse than no file at all, since it actively misleads whatever does read it.
Common Mistakes
Here are common mistakes people make;
- Treating it as a blocking or access-control tool. It has no ability to restrict any crawler. That’s what robots.txt is for.
- Assuming it replaces content quality or schema work. It doesn’t.
- Auto-generating a full-site markdown mirror. Dumping every page into /llms-full.txt at scale risks duplicate content. This can dilute crawl budget and work against the pages you actually want ranking.
- Assuming it helps Google’s AI Overviews specifically. Google has stated directly that it doesn’t use the file for this purpose.
- Never checking whether it’s actually being fetched. Publishing the file and never looking at server logs means you genuinely don’t know whether the effort did anything at all.
Frequently Asked Questions About the llms.txt File.
Here are some frequently asked questions about the llms.txt file;
Question 1: Does llms.txt help with Google’s AI Overviews or regular Google rankings?
No, it does not. Google has stated directly that llms.txt is not necessary for AI Overviews, AI Mode, or any other Google Search feature. It also is not a ranking factor for traditional search results either.
Question 2: Does ChatGPT read llms.txt files?
Rarely, based on current traffic analysis. The crawlers behind ChatGPT’s web search functionality show negligible llms.txt request volume in large-scale log audits. OpenAI does reference the llms.txt format in some of its agent-tooling documentation. However, it is a different use case from ChatGPT’s consumer search product reading it for citations.
Question 3: Is llms.txt a required or official web standard, like robots.txt?
No, it’s no. Adoption by AI providers is entirely voluntary and inconsistent.
Question 4: Can adding an llms.txt file hurt my website?
Not directly from the file itself, but a poor implementation can cause harm. Auto-generating full-site markdown copies of every page can create duplicate content that dilutes crawl budget and works against your existing pages.
Question 5: Who should prioritize adding an llms.txt file right now?
Developer documentation sites, API references, and companies building agent or plugin integrations on platforms like OpenAI’s Agents SDK see the clearest current use case. Most general business websites will get a better return from other AI visibility work first.
Conclusion
llms.txt is a well-intentioned proposal solving a real problem. Again, it is not a meaningful lever for showing up more often in ChatGPT, Perplexity, or Google’s AI Overviews. For most businesses, the honest answer is to skip it for now and put that effort into the signals that will improve your brand’s visibility on AI chatbots. For developer-facing and agent-integrated products, you can put more effort into the llms.txt file.
If you want a clear read on where your specific site’s AI visibility effort is best spent, that’s the kind of evidence-based audit we run at Rankova. Get in touch, and we’ll tell you what’s worth building. In no time, you will be in the face of customers that matter and are ready to buy.
If you enjoyed this, read more here;
Best AEO Agency for E-commerce in Nigeria – SEO & AI Search Optimization Agency
How to Make AI Systems Recognize and Trust Your Brand – SEO & AI Search Optimization Agency
What is schema markup: a plain english guide for business owners
How to Repurpose Old Content to Recover Lost Rankings. – SEO & AI Search Optimization Agency
What Does an SEO Agency Actually Do Day-to-Day? – SEO & AI Search Optimization Agency
Internal Linking Strategy: The Most Overlooked SEO Tactic. – SEO & AI Search Optimization Agency
Pingback:How to Get Cited by Google AI Overviews - SEO & AI Search Optimization Agency